High-Performance Spark Engine for Modern Data Teams
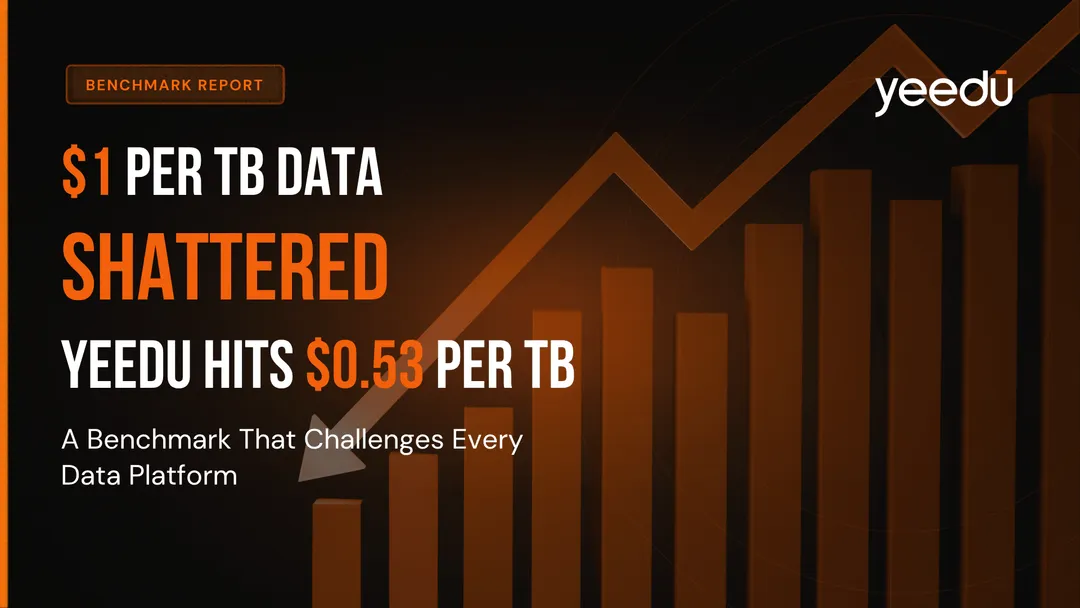
Run critical pipelines 4–10× faster, reduce cloud spend by 60–80% with no code refactoring or vendor lock-in.

Traditional Spark engines weren't built for today's scale
Bill shocks from undersized clusters
Undersized clusters waste compute and create unpredictable, painful bill shocks at the end of every month.
Developer overhead
Complex interfaces slow teams down and add engineering overhead just to keep pipelines running.
Proprietary platform lock-in
Usage-based pricing on proprietary platforms locks teams in and punishes growth instead of rewarding it.
Key Features: What Makes Yeedu a High-Performance Spark Platform
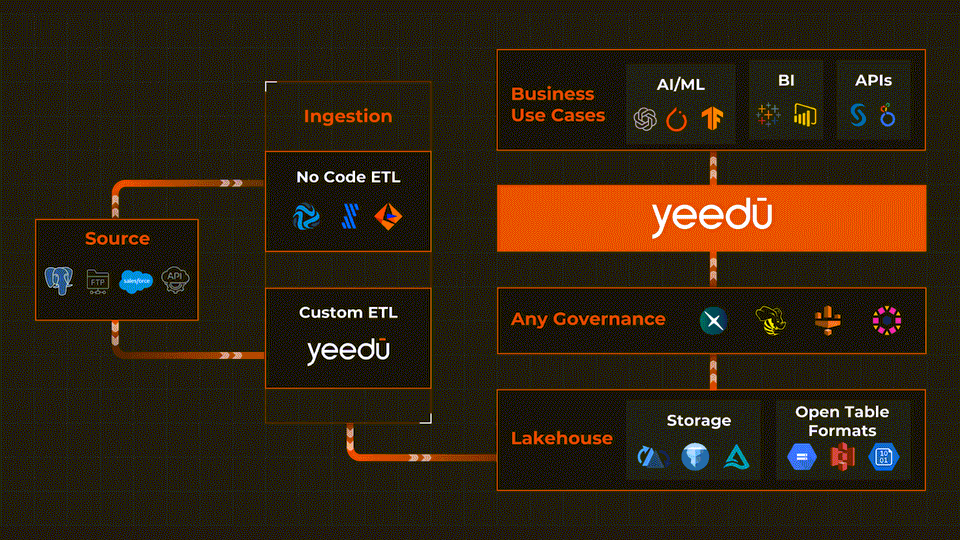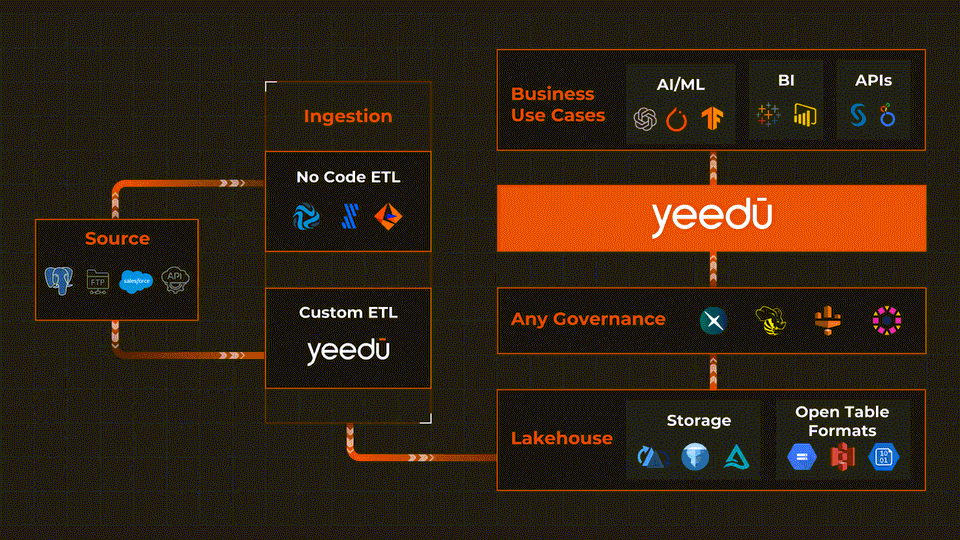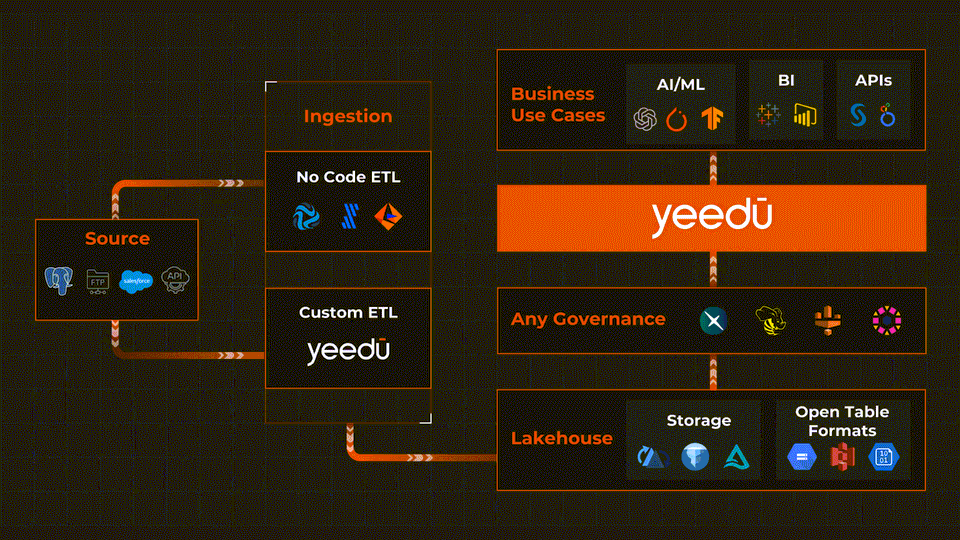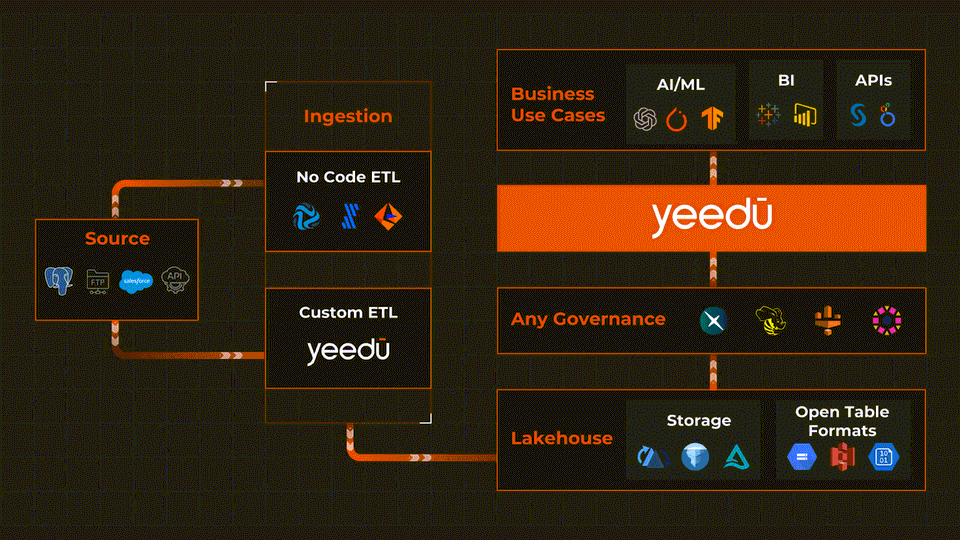
Built to Run Parallel With Every Spark Platform, Cloud, and Catalog
Native integrations for orchestration, monitoring, cataloging, and AI services.
Enterprise-ready deployment in minutes
- SOC 2 Type II equivalent security posture
- Built on open-source Spark with enterprise-grade governance
- Multi-cloud & hybrid support: AWS, Azure, GCP, Kubernetes
- Zero vendor lock-in: everything remains portable and open
AWS EMR
Move high cost EMR workloads to Yeedu with no code rewrite
Fully supported
Databricks
Shift off usage-based licensing, run your critical pipelines 4–10× faster
Fully supported
Google Dataproc
Lower compute costs significantly
Fully supported
Cloudera
Migrate from legacy clusters to a modern, high-performance Spark engine
Fully supported
What Our Customers are Saying
Rising data platform costs are among the biggest challenges enterprises face today. Yeedu provides a transformative solution that drastically reduces expenses and eliminates this critical barrier, empowering organizations to focus on driving innovation and achieving their goals.
Dr. Mark Ramsey
Ex-Chief Data Officer, GSK & Samsung Mobile
That's Why We Built Yeedu Differently
Recent Articles

Talk to sales
Let's help your team build better
Get demo
Discover how Yeedu empowers your team
Enterprise trial
Try Yeedu to simplify your workflow
Custom solutions
Get advice tailored to your team's goals
Frequently Asked Questions
Everything you need to know about pricing, migration, and how Yeedu fits alongside your existing data stack.
Yeedu offers a tiered licensing model, with monthly fees starting at $2,000. Pricing increases with higher usage tiers, ensuring scalability and cost efficiency.
Yeedu supports open-source Apache Spark, and your PySpark and Scala jobs can be migrated “As-Is” to Yeedu. It also supports Python 3+.
No, Yeedu supports open-source Apache Spark. Jobs can be written in PySpark or Scala and migrated to other platforms as needed, ensuring flexibility.
Yeedu has helped enterprises cut costs by an average of 60%. To evaluate potential savings, you can start by onboarding a sample workload.
Yes, Yeedu can run any Python job written in Python 3+, including those using popular modules like pandas.
Yeedu is a data platform that creates and runs data processing workloads like Databricks and Cloudera. However, Yeedu works well with Databricks and Cloudera's governance setup, so rather than a full workload migration, customers can start migrating high-cost workloads to Yeedu to maximize their cost savings. Over time, more workloads can be migrated as customers see value.
Yeedu supports Python, Scala, and Java jobs and provides optimal performance for Spark workloads. It is designed to enhance Spark application efficiency and cost savings.
No, there are no minimum thresholds. Yeedu delivers noticeable cost savings when a mix of low, medium, and heavy workloads are run on the platform.
Yeedu runs entirely within your cloud account, under your firewall. You do not need to export data outside your environment.
Existing Python, Scala, and Java jobs can be onboarded to Yeedu by uploading the code files. If your jobs are in notebook format, they can be easily migrated to Yeedu’s notebook editor and executed seamlessly.
Still have questions?
Can't find what you're looking for? Talk to our team and we'll walk you through how Yeedu works for your workloads.
Schedule a Chat