The Challenge
A global financial services company was facing a common but costly problem: their mission-critical data processing workloads were consuming an increasingly large share of their cloud infrastructure budget. With strict SLA requirements and growing data volumes, costs were becoming difficult to justify.
Two workloads in particular were driving the majority of their data infrastructure spend:
Real-Time Streaming Pipeline
A complex streaming job that processes incoming JSON files with a strict SLA of under 5 minutes per file. The pipeline handles approximately 1,500 files daily, each undergoing 32 transformations before records are written to Delta tables.
- 57 folders containing 127 Python files (~18,000 lines of code)
- 400 JSON configuration files defining transformation logic
- Required 4 worker nodes during peak hours to maintain SLA compliance
Cross-Region Data Replication
A data replication job responsible for synchronizing data lakes in Delta format between AWS regions (us-east-1 to eu-east-1) every 2 hours, ensuring business continuity and regional compliance.
- 7,223 tables in scope for replication
- 7,679,367 S3 objects totaling 1.9 TB of data
- Required dedicated driver and worker instances running continuously
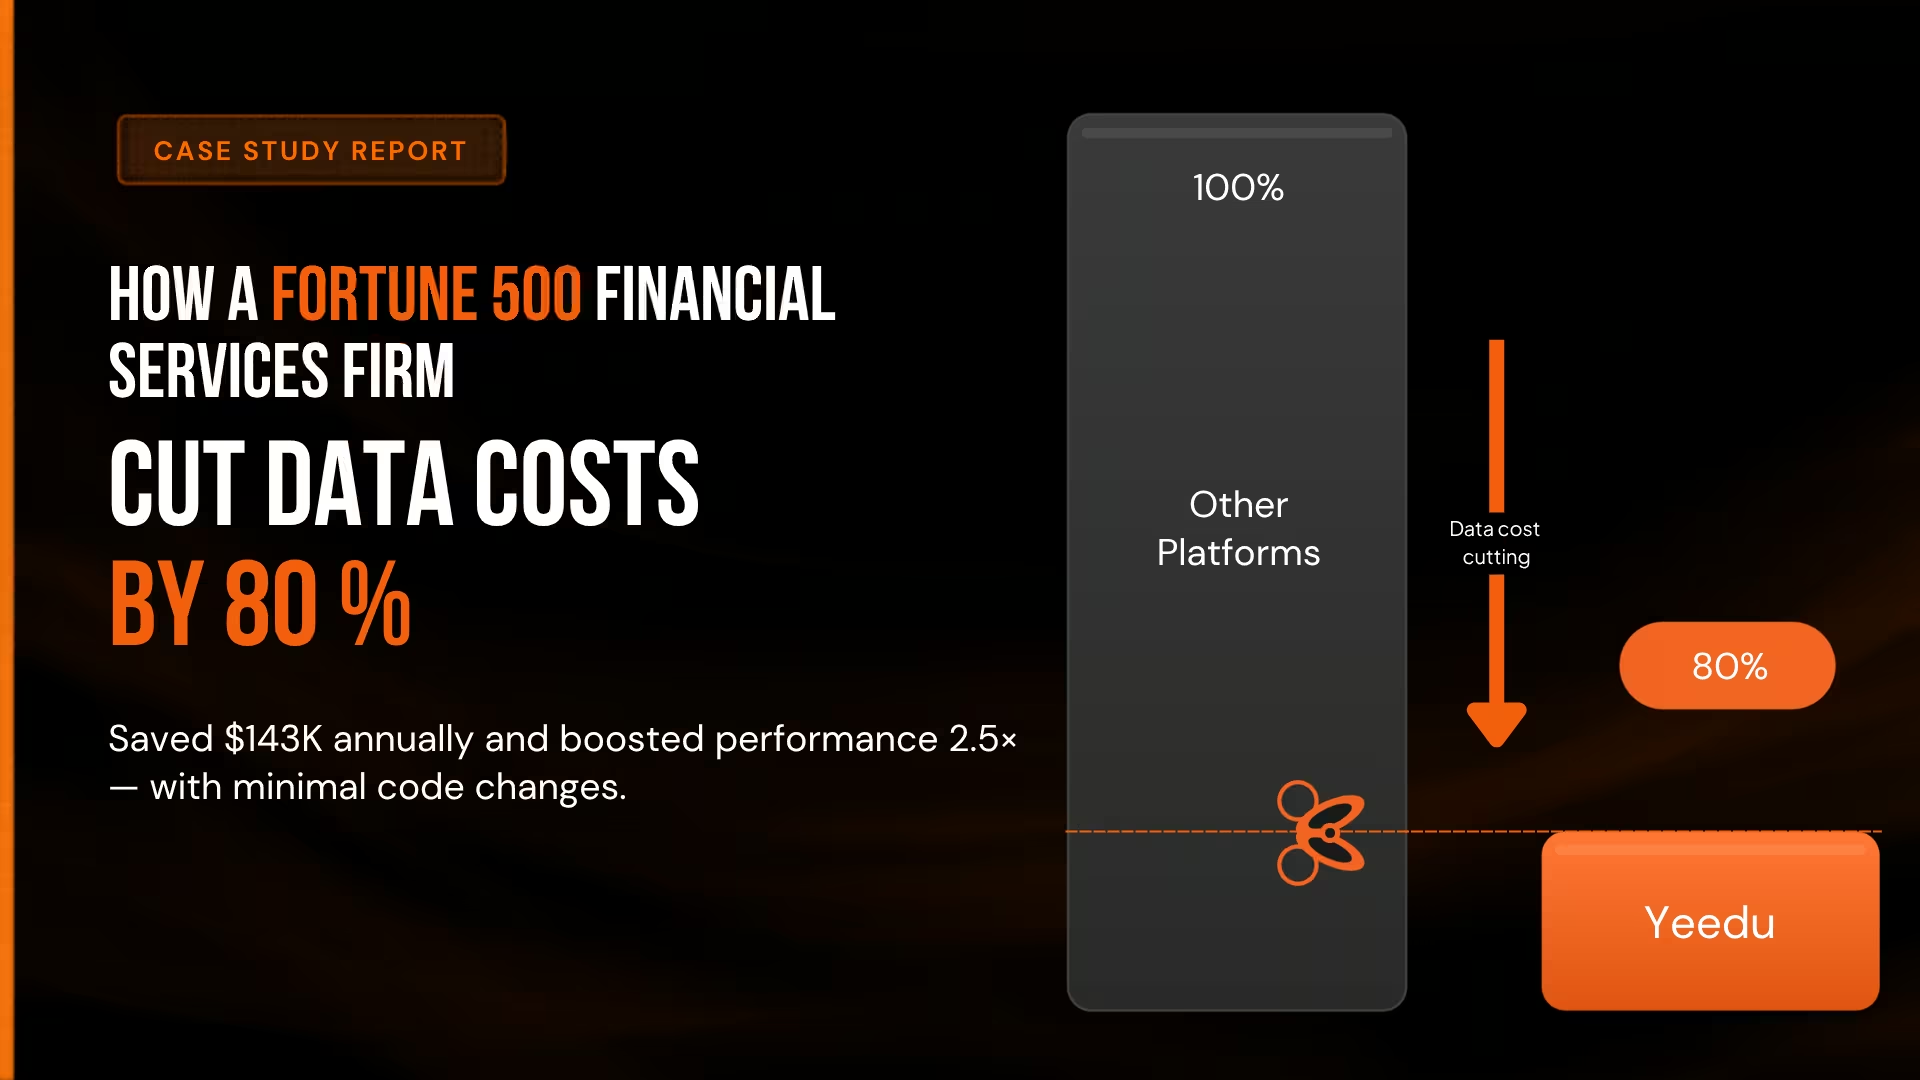
Combined, these two workloads were costing the organization over $180,000 annually in compute and licensing fees and costs were projected to increase as data volumes continued to grow.
The Solution
The company integrated Yeedu alongside their existing data infrastructure. Rather than a disruptive migration, they strategically redirected their most expensive workloads to Yeedu while maintaining their current governance and data architecture.
One of the key advantages was how little modification was needed to run existing Spark workloads on Yeedu:
# Streaming Pipeline Migration: 6 lines changed

+ Updated environment configs (bucket name, catalog name)
+ Added 4 lines for Yeedu CloudFiles streaming (parallel processing)
+ Added 2 lines for Python path imports

# Data Replication Migration: 10 lines changed

+ Minor adjustments for open-source Spark compliance
+ Thread pool performance optimizations
Yeedu's Turbo Engine delivered such significant performance improvements that the company was able to dramatically simplify their infrastructure replacing multi-node clusters with single-instance configurations while eliminating the need for auto-scaling.
We expected cost savings, but we didn't expect to also see performance improvements. Getting both simultaneously changed how we think about our entire data infrastructure strategy.
By the Numbers
Streaming Pipeline: Production Cost Comparison
| Platform | Annual Cost | Savings |
|---|---|---|
| Previous Platform | $143,523 | – |
| Yeedu (x86 instances) | $31,676 | $111,847 (77.9%) |
| Yeedu (Graviton instances) | $28,506 | $115,017 (80.1%) |
Data Replication: Performance Comparison
| Platform | Execution Time | Tables Processed | Annual Cost |
|---|---|---|---|
| Previous Platform | 100 minutes | 4,100 | $37,668 |
| Yeedu (Graviton) | 39 minutes | 7,200 | $9,252 |
Total Annual Savings
| Workload | Annual Savings | Reduction |
|---|---|---|
| Real-Time Streaming Pipeline | ~$115,000 | ~80% |
| Cross-Region Data Replication | ~$28,000 | ~75% |
| Total Combined Savings | ~$143,000 | 75–80% |
The Results
Immediate and substantial improvements across both performance and cost metrics.
Streaming Pipeline
Annual savings of $115,000 with 25% faster processing (75 seconds vs. 112 seconds per file).
Data Replication
Annual savings of $28,000 with 2.5x faster execution (39 minutes vs. 100 minutes).
Infrastructure
Single-instance configurations replaced 4-node clusters, eliminating auto-scaling complexity.
Migration Effort
Total code changes required across both workloads preserving existing business logic.